Real-time lip sync
The face speaks as the audio streams, in 1K resolution. No render jobs, no polling, no clips to wait for.
FaceMode turns your agent's audio into a live, lip-synced avatar.
No new voice stack. No video pipeline to build.
[ Same voice, two ways ]
Bring any voice pipeline. If it streams audio, FaceMode gives it a face.
[ How it works ]
From the first audio frame to a rendered face on screen - four stages, one continuous low-latency path.
One REST call returns the room binding and a one-time credential for the audio socket.
Pipe the audio your agent already produces, about 100ms at a time. No client-side resampling.
FaceMode generates lip-synced video frames and publishes them into your room as an ordinary participant.
Subscribe with the LiveKit or Daily.co client SDK you already ship. Nothing new on the frontend.
[ Setup prompt ]
Paste it into the coding agent you already use. It reads the FaceMode docs, checks your project, and adds FaceMode with our LiveKit plugin, Pipecat plugin, or direct API. It shows you the plan before it edits anything.
Read the integration guides[ What you get ]
FaceMode does one job. It turns the audio your agent already produces into a talking avatar, in the room you already own.
The face speaks as the audio streams, in 1K resolution. No render jobs, no polling, no clips to wait for.
Your agent decides when the user has cut in. Send one cancel message and the avatar stops the current utterance. The LiveKit Agents and Pipecat plugins send it automatically.
On LiveKit Agents or Pipecat, install the plugin and keep writing agent code. On anything else, create a session over REST and stream audio. Any language that holds a socket open works.
Between utterances the avatar keeps blinking and breathing, then crossfades into speech. No freeze-frame, no state handling on your side.
[ Avatars ]
Pick a face from the library or upload your own portrait. FaceMode lip-syncs all five styles the same way.
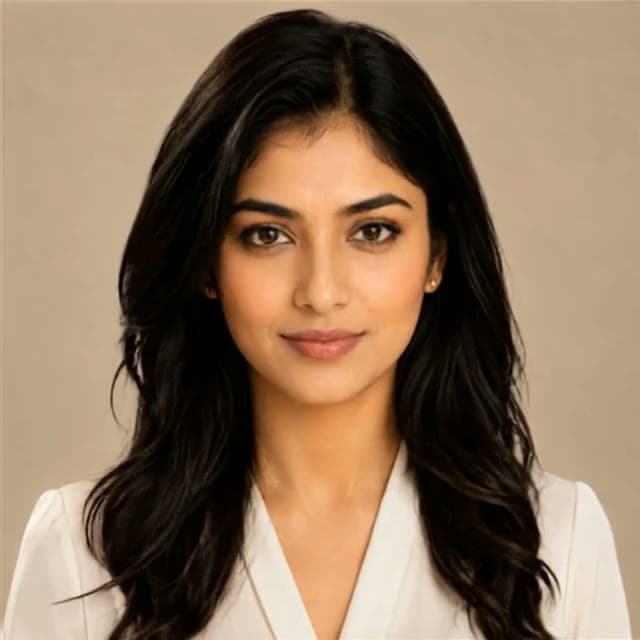
Editorial-grade human portraits.
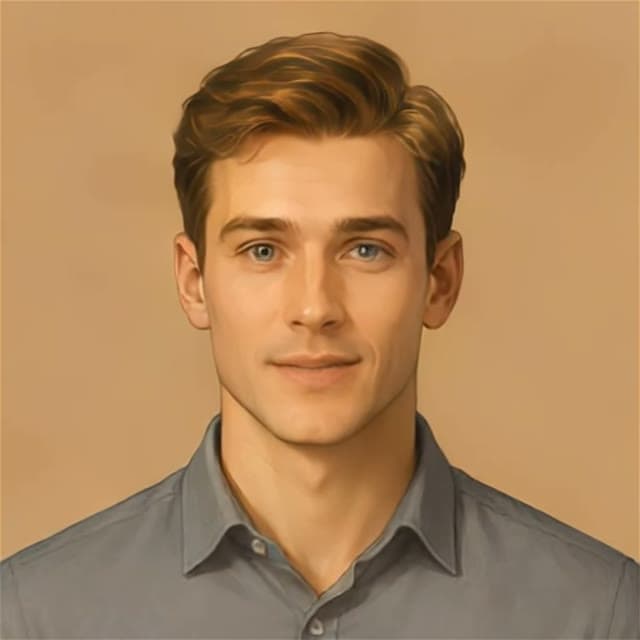
Human, gently stylised.
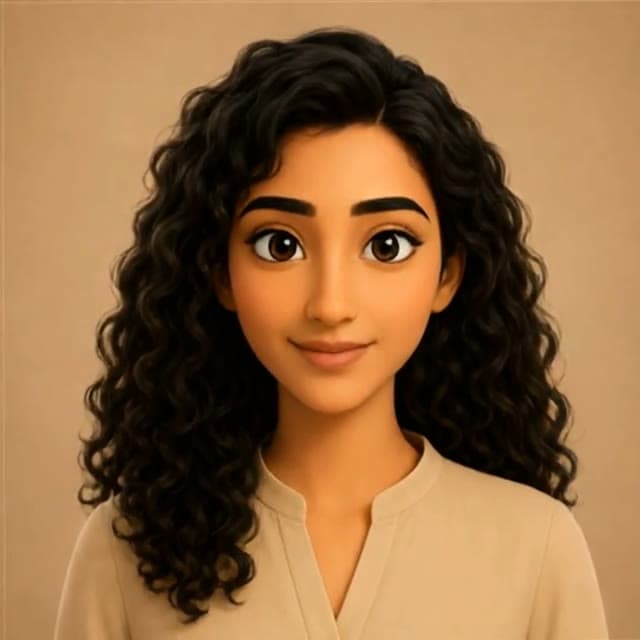
Smooth, warm, character-friendly.
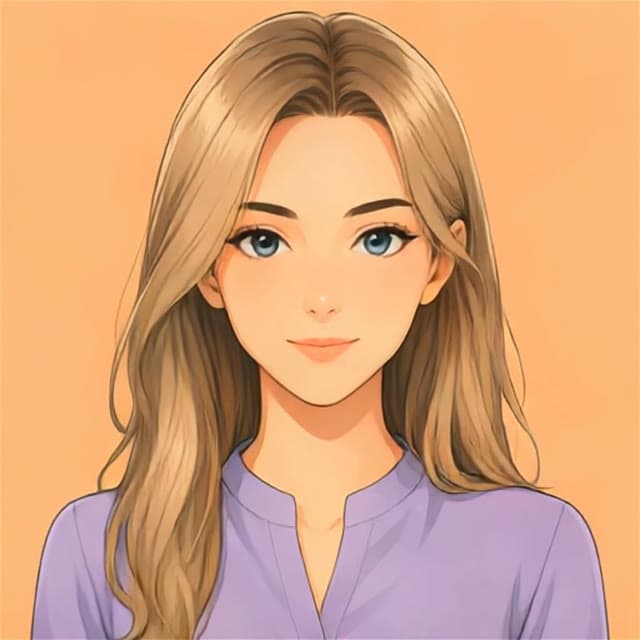
Cel shading and crisp linework.
Minimal shapes, brand-safe.
Bring your own face. Upload one front-facing portrait and it becomes an avatar.
[ Why a face helps ]
Add a face where customers already look - training, intake, guidance, and live help. Every claim below comes from published research.
Healthcare, randomised controlled trial
0.0%
Knowledge gain, against 3.7% without
0.0%
Patients satisfied with the session
Patients taught by an avatar gained six times more knowledge than a control group - and nearly all of them said they were satisfied.
Journal of Advanced Nursing
And in every other sector studied
Education
Learners learn more, stay motivated
Review of Educational Research
Support
Answers get richer, and come faster
Behavior Research Methods
Sales
Buyers report stronger intent to buy
Journal of Marketing
Guided tasks
People look longer, act faster
Frontiers in Robotics and AI
Advisory
Facilitators build more trust
ACM CHI
[ Private Beta ]
We are letting teams in a few at a time. Approved testers get 60 minutes of avatar video to build against the full API. No card, no subscription.
Beta access
Approved beta testers get 3,600 credits - 60 free minutes of streamed avatar video - to build and test with the full API.
[ Questions ]
No. FaceMode takes the audio your stack already produces. Your STT, LLM, TTS, and turn detection stay exactly where they are.
You do. You create a LiveKit or Daily.co room and hand FaceMode a token to join and publish. FaceMode never sits between your app and your room.
Install the plugin. It creates the session, opens the audio socket, and reconnects on drops. Python and JS for LiveKit Agents, Python for Pipecat.
Create a session over REST, open a WebSocket, stream audio. Any language that can hold a socket open works.
Yes. Stop sending audio and the face crossfades back into its idle loop instead of freezing, then picks straight back up.
Upload one front-facing portrait and it becomes an avatar. Or pick from the library across five art styles.
Credits, not seats or subscriptions. One credit is one second of streamed avatar video. FaceMode is in beta right now - top-ups for extra credits open once we hit general availability.
[ Ready when you are ]
Your agent already knows what to say. Spin up a session and let people watch it say it.